I built my own operating system with Claude Code: it pulls data from the systems I work in, turns it into dashboards, and runs the repetitive administration on a schedule.
Any interface shown is a de-identified demo. All figures are illustrative and contain no real client or personal data.
Ad performance in one console, orders in another, tasks in Notion, schedule in a calendar. Opening each one, copying the numbers out and assembling something decision-ready took most of the morning — and it was stale again the next day.
Capability (what it can do), workflow (when it runs) and memory (what it decides against) are stored separately. This is what keeps maintenance cost down.
Deployment is a mounted-config setup: one version-controlled core directory, symlinked into place. New machine, pull it down, run the mount script, run the health check. A full day of rebuilding becomes five minutes.
These are not mockups. The dashboard was run against a structurally identical dataset with every value and label replaced by synthetic ones, then screenshotted — so the layout, fields and charts are exactly what the system renders, while nothing on screen is real. No redaction, no blurring.
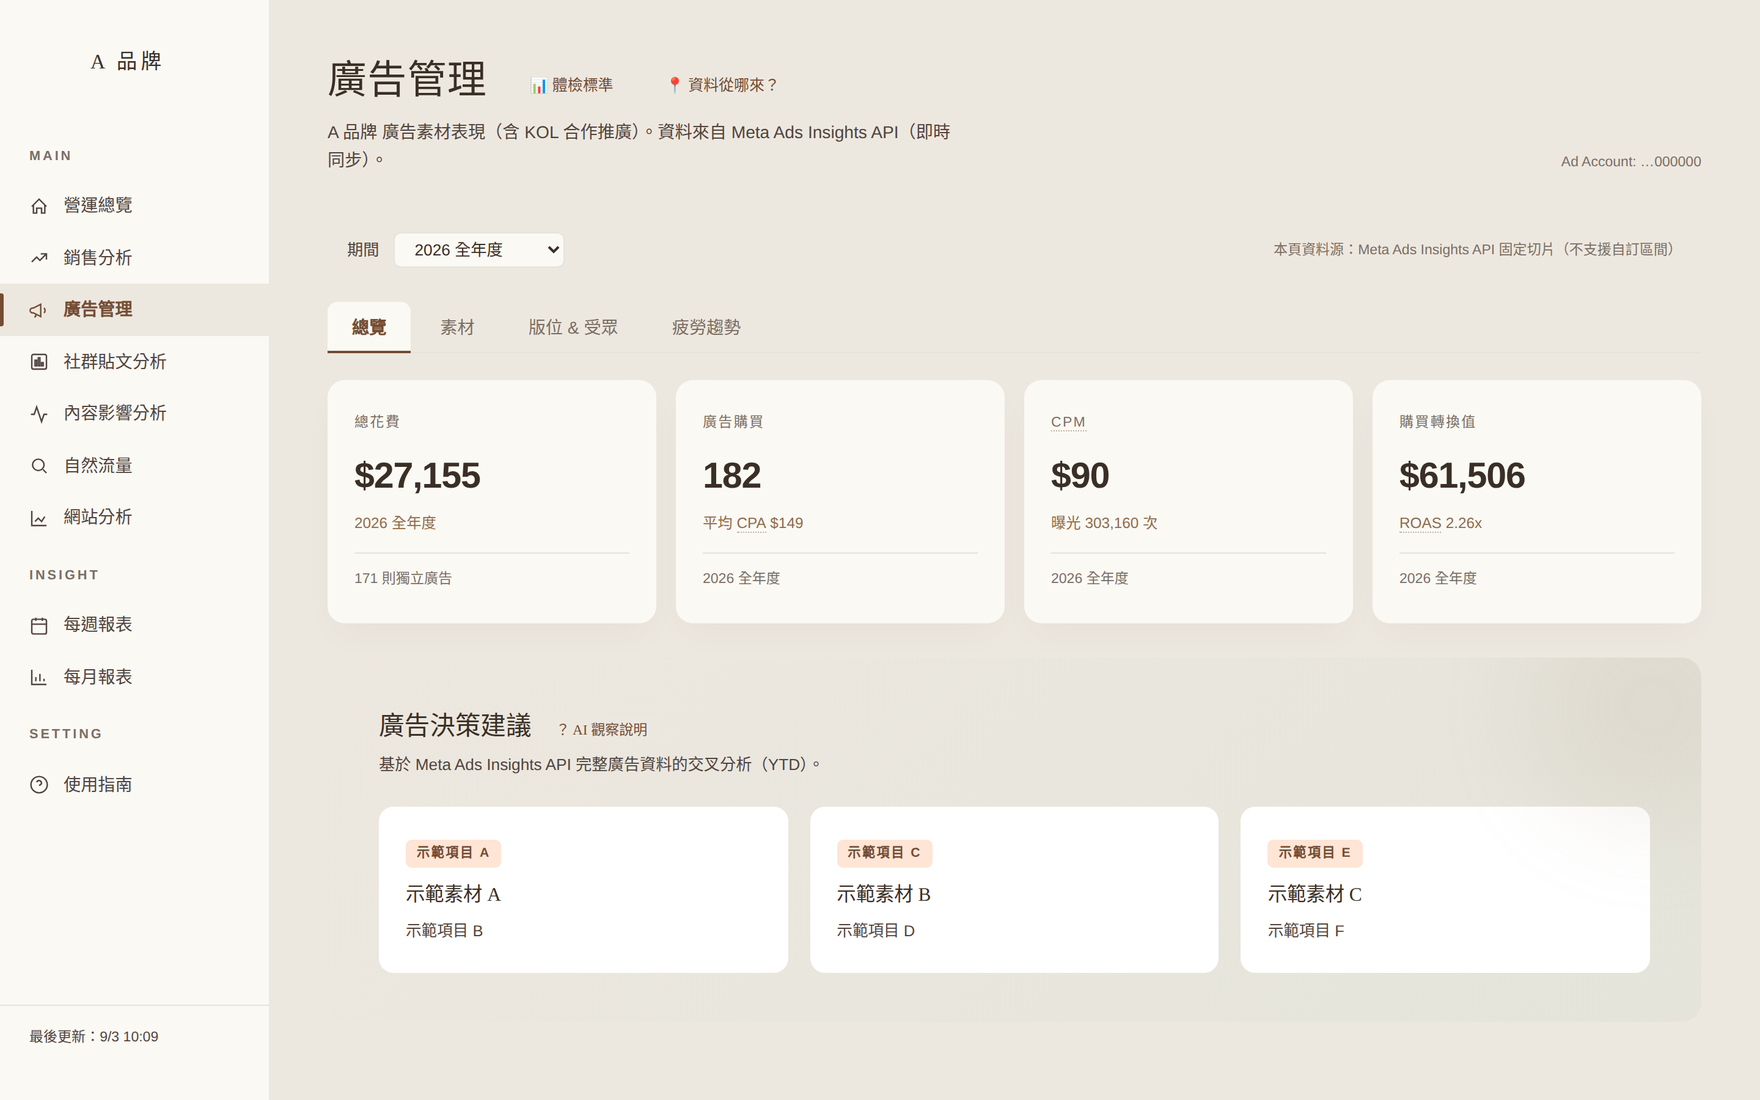
Paid media. Spend, orders and performance pulled from the ad platform API into the handful of numbers worth watching daily, with scale / pause / replace-creative recommendations derived from them.
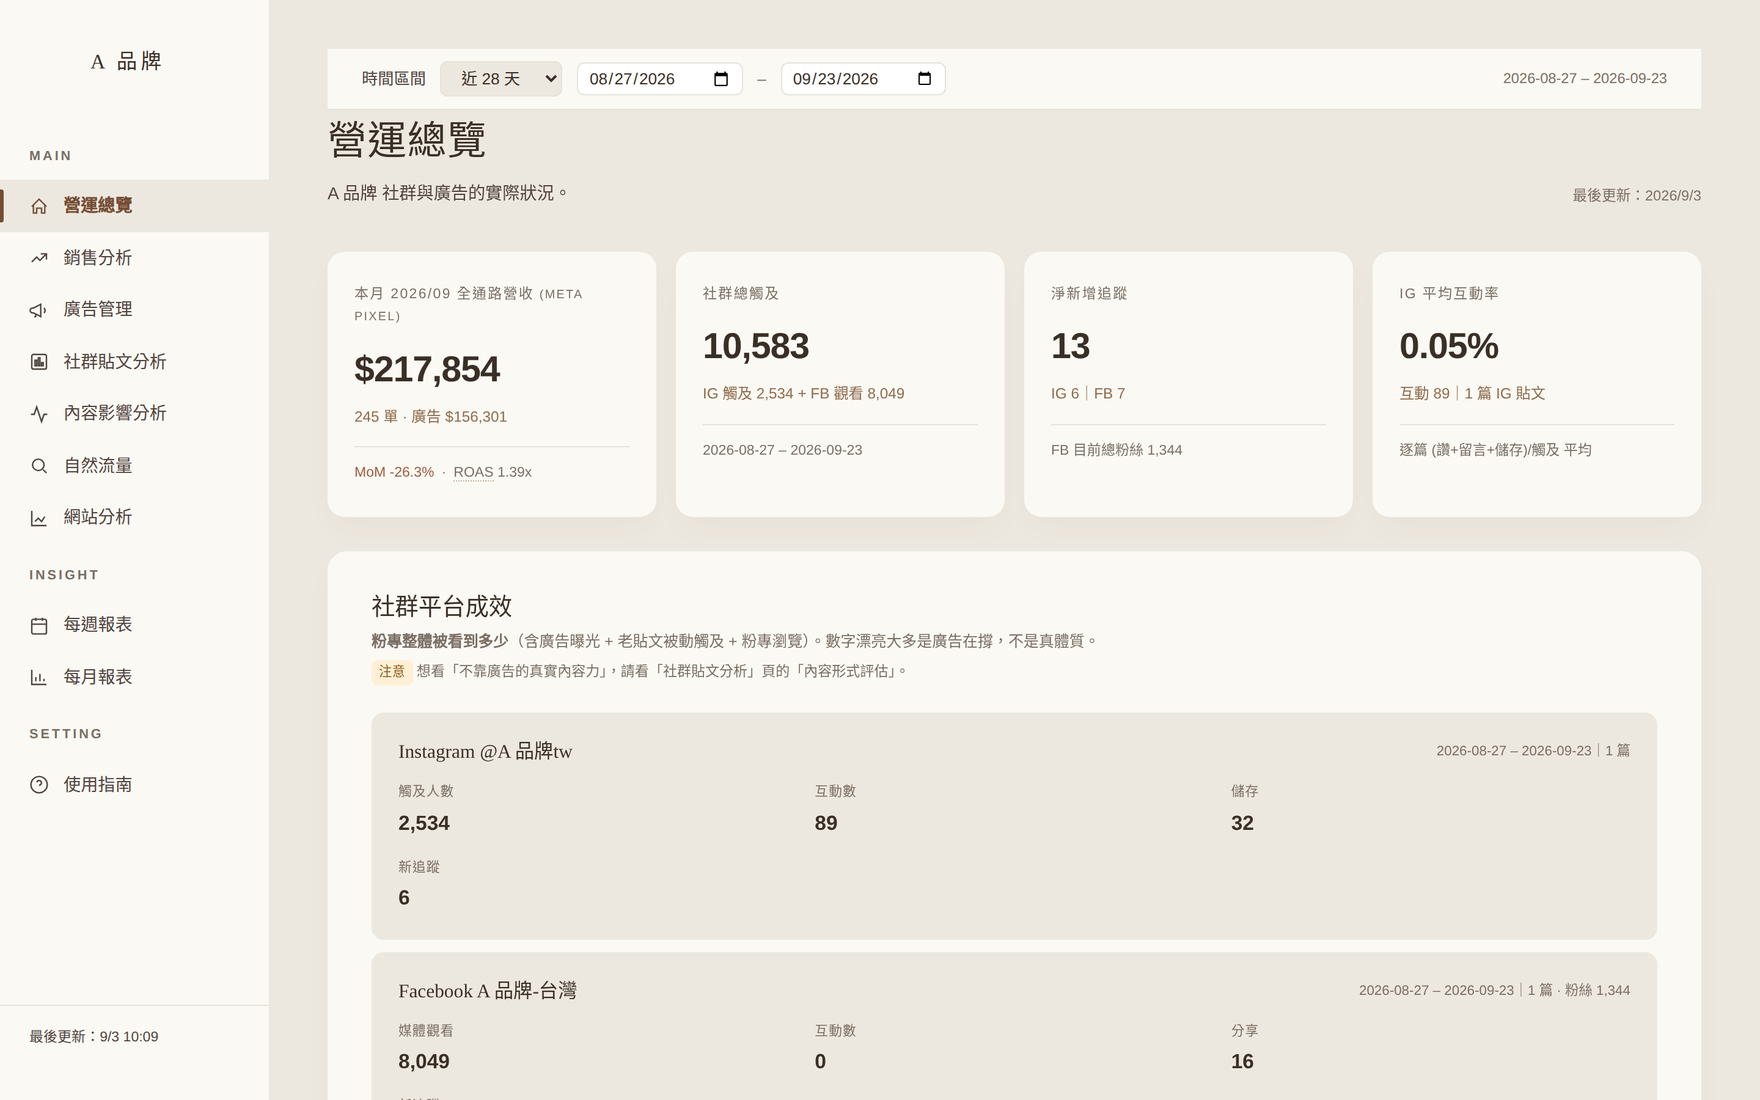
Operations overview. Social, paid and sales in one view. Each figure carries its basis and coverage — "revenue" can mean three different things in the same report, and unlabelled it gets used to reach the wrong conclusion.
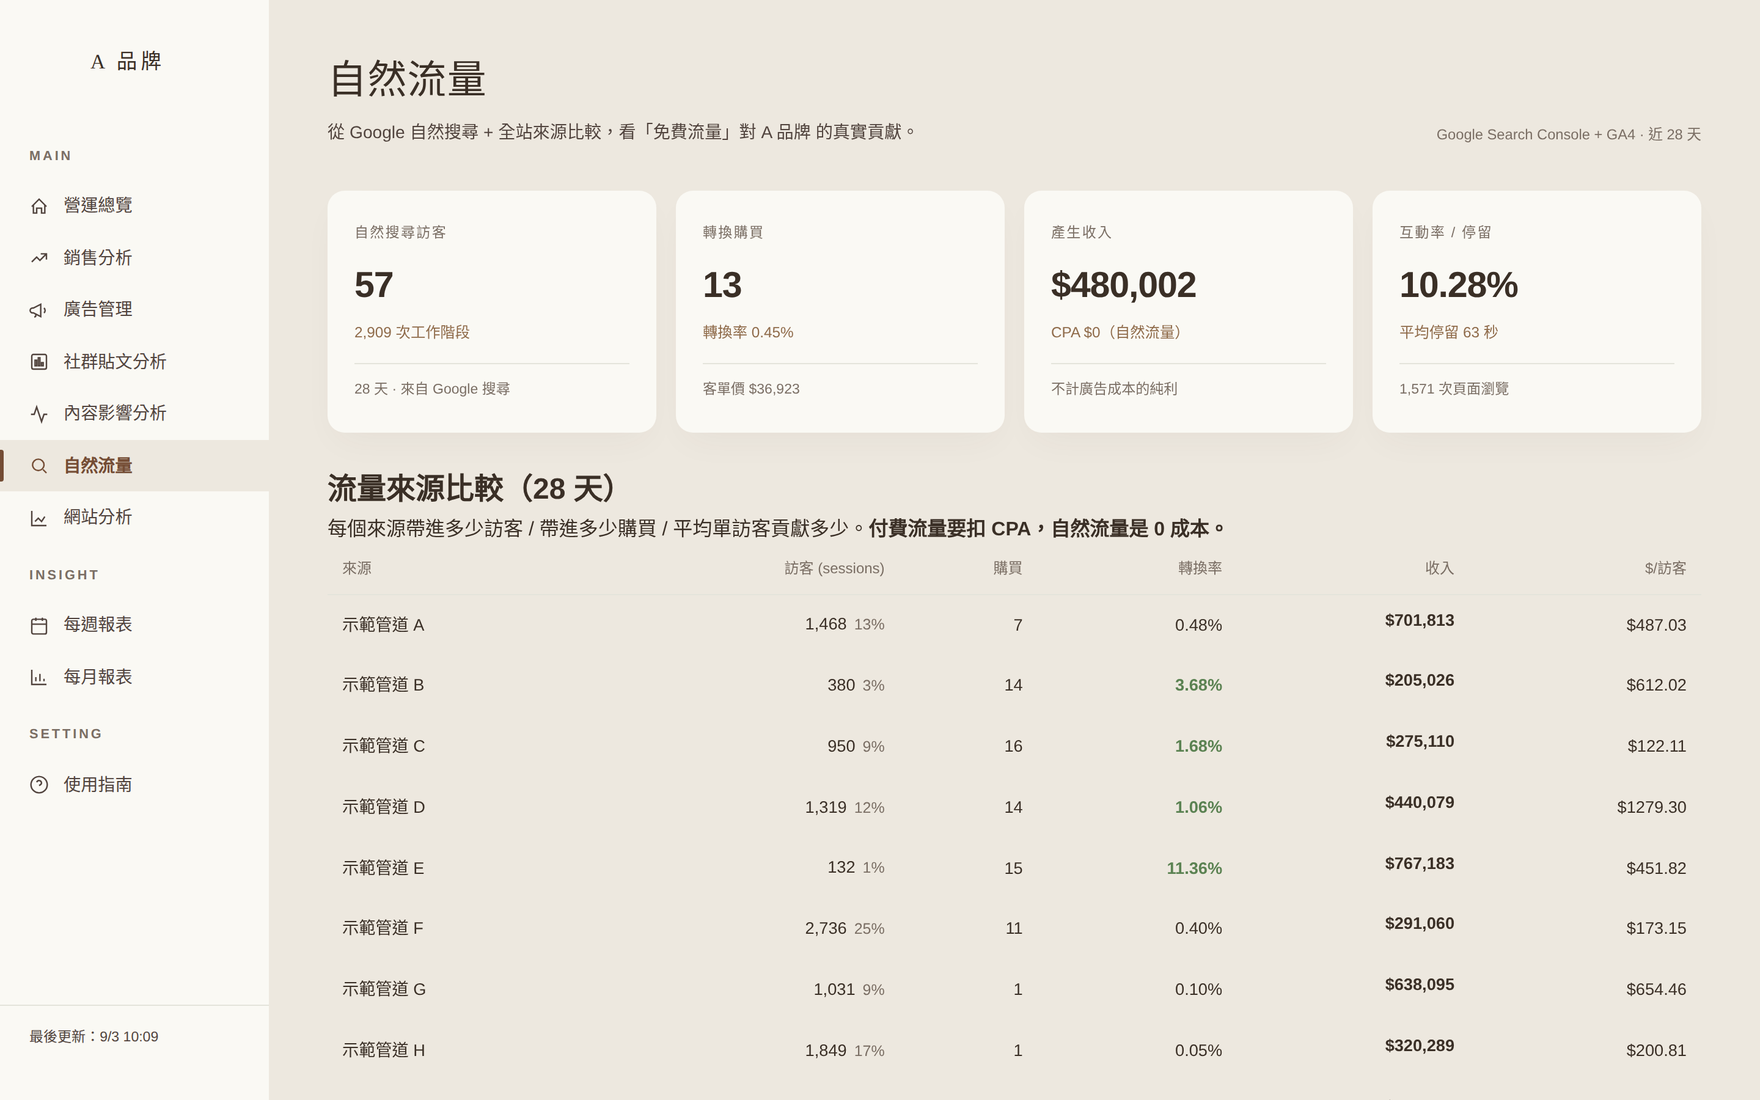
Organic search. Search console and web analytics, used to decide whether resource goes to search or to paid. This view is what moved budget toward search: organic contributes roughly 4× per visitor what paid social does.
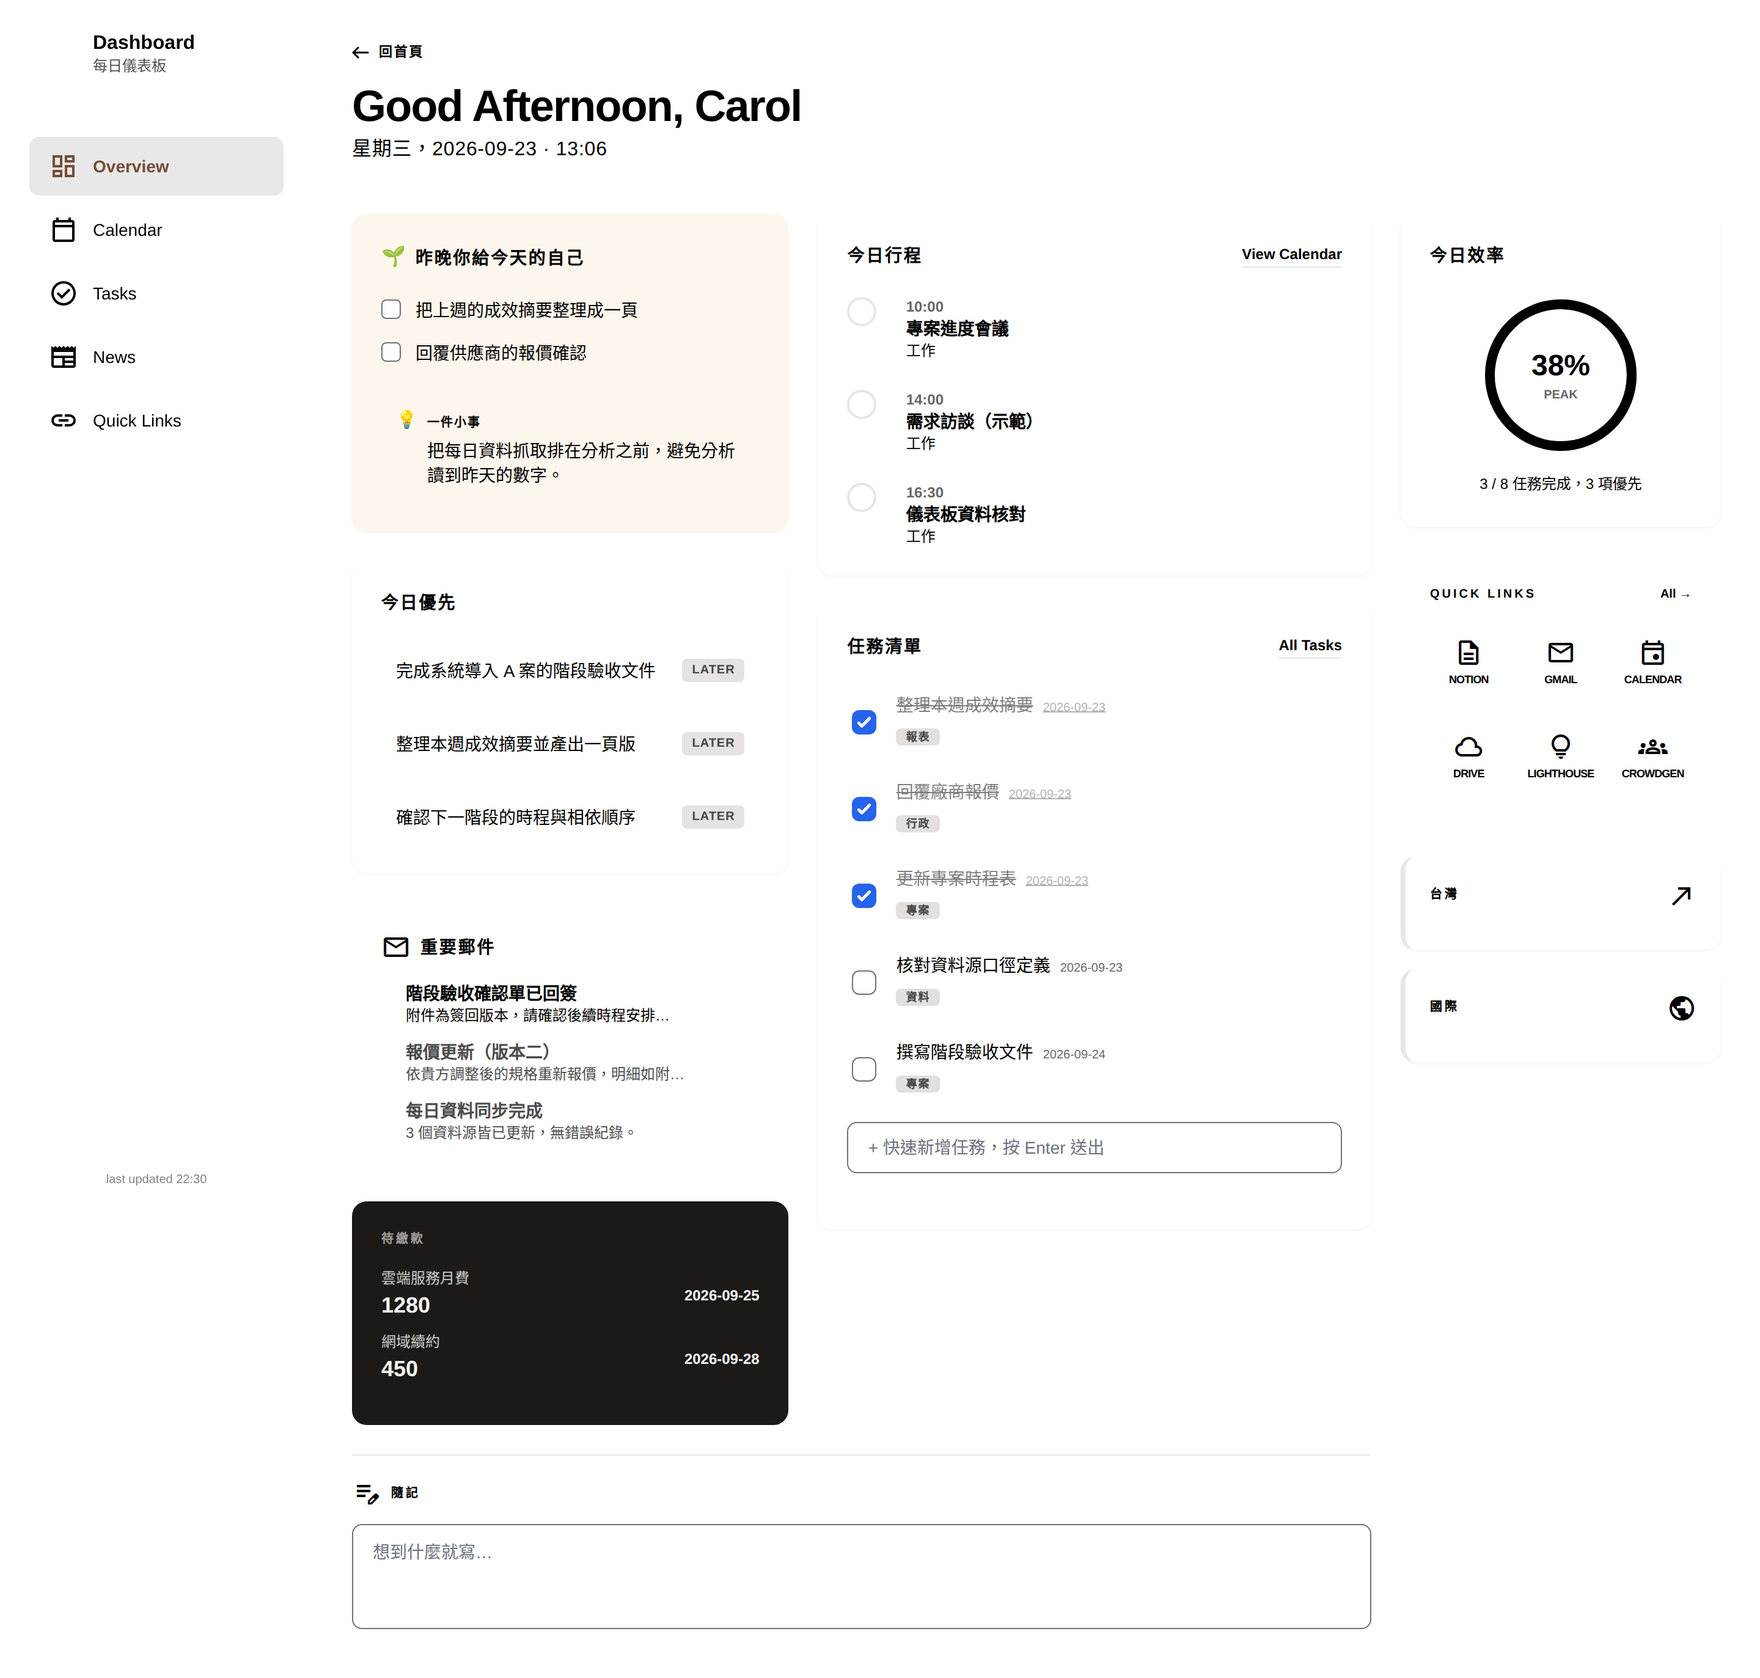
Daily brief. Calendar, tasks, priority mail and upcoming payments assembled into one page every morning. The panel top-left carries forward the three things written down the night before — closing the loop between reflection and execution rather than leaving two sets of notes that never meet.
Automating something that isn't trustworthy yet only scales the error.
These three are worth more than the module count.
The scheduler reported "not logged in" while the identical command worked in my own terminal. The cause was the operating system deliberately isolating background processes from the user keychain — a security design, not a fault, so "fix it" was never an option.
Resolution: moved to a long-lived authorisation token, and specifically chose the variety that cannot trip metered API billing. That choice carried real financial exposure, so I verified the billing model before making it.
There is nobody in a scheduled environment to answer "save this file?", so the whole run stalled. This class of error never appears in manual testing, because in manual testing I am sitting there.
Resolution: ran a full end-to-end simulation, which surfaced two environment-specific faults — one waiting on a save prompt, one silently renaming its output so the downstream job couldn't find it. Turned it into a standing rule: modules that run on a schedule must specify three things — write directly, never prompt, fixed filename prefix.
An external service expires its authorisation every seven days. I believed a configuration change had solved it permanently; a week later reality disagreed. Checking the provider's actual policy confirmed there was no fix available for an account of my type.
Resolution: stopped trying to eliminate it and reduced its cost instead —
a one-command re-authorisation script, plus monitoring that tells me which script to run when it lapses.
A second lesson came with it: monitoring file timestamps is unreliable, because the file still gets written
when the service behind it is dead. Checking the error records inside the file is what actually catches it.
The expensive part of running projects is rarely the decision. It's assembling, reconciling and aligning information before the decision can be made. That is the part I automate.
Which is the same thing systems implementation is: taking a process that only works because someone is holding it together, and making it run on its own.